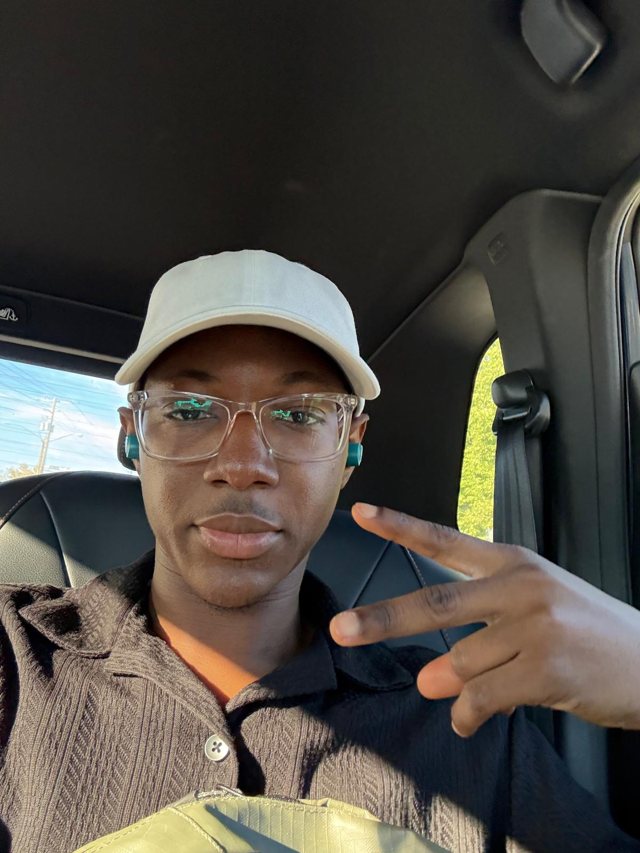
Ayokunmi Lawal
I'm a data science student at York University in Toronto. I build machine learning and analytics projects, mostly around football, and I put the real numbers on them, including the ones that come out worse than I hoped.
About
Available for a 4 month internship from January 2027, Toronto.
I like taking messy public data and turning it into something a person can open and use: a dashboard, a map, a shortlist, a report. Football is where I started, so a lot of it points there. Some of it points at housing and public health instead.
Everything below is in public repos with dates on the results. When a model does not beat the simple baseline, the README says so. That habit has saved me from a few flattering mistakes, and I would rather you hear about them from me.
Work
Four projects. Open What I did for the situation, task, action and result. Each links to the code and the measured results.
2026Sports analytics
Football player undervaluation model with a RAG scouting assistant
Built end to end
A model that flags players who moved into a top five league and may have been undervalued, plus a chat assistant a scout can ask about them. It cuts a league down to a shortlist of 100 names.
- Python
- scikit-learn
- PyTorch
- PostgreSQL
- LangChain
- LangGraph
- Docker
- AWS
What I did
- Situation: A scout has to look through a whole league, 170 to 300 eligible players, to find who might be worth a closer look.
- Task: Build a model that only uses what was known before each transfer, and an assistant that answers scouting questions with sources.
- Action: Put 1,725 moves from nine leagues into the top five into PostgreSQL. I dropped 56 with no appearances in the year before, which left 1,669 usable records.
- Action: Trained logistic regression, gradient boosting and a PyTorch neural network. The neural network scored best on validation (AUC 0.764), so it ranks the shortlist.
- Action: Built a LangGraph and LangChain agent that sends each question to stats or to written reports, and answers with citations. Packaged it in Docker and ran it on a small AWS server.
- Action: Added computer vision on maps of past player actions to see whether it made answers better.
- Result: In a backtest, the top 20% by predicted probability became regular starters 56.7% of the time, against a 30.9% base rate. The models beat a constant guess clearly but beat a simple minutes played rule by only about 0.03 to 0.04 AUC, so I do not claim they are clearly better.
- Result: The assistant answered 9 of 10 held out questions correctly and cited real sources every time. Ten questions is a small test, and the README shows how wide the interval is.
- Result: Vision did not improve accuracy on the main benchmark. It only helped on questions that could be answered from the maps alone.
Limit: market value is Transfermarkt's estimate and fees are not used, so undervalued is not proven by this data.
2026Sports analytics
Premier League match prediction pipeline
Built end to end
A pipeline that refreshes fixtures and form on a schedule, predicts upcoming matches and publishes them to a live dashboard. A weekly job retrains and checks the model against past seasons.
- Python
- PySpark
- scikit-learn
- GitHub Actions
What I did
- Situation: I had a weighted model I wrote by hand to predict matches, and no check of how it did on past seasons.
- Task: Add a trained model, test it honestly against a simple baseline, and keep the whole thing running without me.
- Action: Built the form features in PySpark from each team's previous 5 matches, so a match never sees its own result.
- Action: Trained logistic regression and gradient boosting, always on earlier seasons only, and tested on 5 seasons from 2021/22 to 2025/26.
- Action: Scheduled it on GitHub Actions: daily, hourly on match days, and a weekly run on Mondays that rebuilds the features, retests the model and writes new predictions. Fixed a bug where recent results were fed to the old model in the wrong order.
- Result: Logistic regression scored between 47.5% and 54.7% a season, 49.9% over all five. Always picking the home team scored between 41.1% and 48.3%, 44.2% over all five.
- Result: With 375 matches a season, one standard error is about 2.5 points, so most season to season differences are noise. My hand written weighted model is roughly as good, which I report as it is.
2026Public data
Toronto housing and shelter forecasting pipeline
Built end to end
A tested data warehouse that links Bank of Canada interest rates to Toronto shelter occupancy, with forecasts on top. The main finding is that shelters are so full that forecasting adds little.
- dbt Core
- DuckDB
- Python
- statsmodels
What I did
- Situation: Toronto shelters run close to 98% full. I wanted to know if interest rate changes show up in shelter demand.
- Task: Build a reliable data foundation, then test whether the rate helps forecast occupancy better than simply repeating the last period.
- Action: Pulled five public sources into a dbt and DuckDB warehouse: a 433K row fact table with 26 automated tests.
- Action: Ran a regression, then SARIMA and Prophet forecasts against a naive baseline.
- Action: Added a monthly model with the policy rate as an input, lagged 6 months. I fixed that lag before running it and judged it on a held out period from 2024 onward.
- Result: Occupancy rose about 0.64 percentage points for every 1% rate increase, roughly six months later.
- Result: The forecasts did not beat the naive baseline. The rate model was 0.6% worse, with an average error of 0.425 percentage points against 0.422. A full system leaves little to predict, and that is the finding.
2026Public health
Toronto shelter overdose spatial analysis
Built end to end
A companion to the housing project that asks what predicts where overdoses happen across Toronto's 158 neighbourhoods, and whether the clusters are real.
- Python
- geopandas
- PySAL
- scikit-learn
What I did
- Situation: Overdoses in Toronto shelters looked clustered on a map, which could guide where outreach goes.
- Task: Find out what actually explains where they happen, and whether the clusters hold up.
- Action: Matched shelter addresses to neighbourhoods. I could place 114 of 151 addresses, which cover about 84% of incidents. The rest are left out and the README says so.
- Action: Used regression with neighbourhood income, then a machine learning layer, then density clustering and a hotspot test (Local Moran's I).
- Result: Low income prevalence explained most of the apparent clustering. The machine learning layer cut cross validated error from about 52 to about 33 incidents per neighbourhood.
- Result: Clustering found 6 clusters at settings I fixed before running it, but anywhere from 1 to 9 across other settings, so I do not treat the count as fixed. The hotspot test found one connected group of 9 neighbourhoods.
Experience
Aug 2026 to Present
Sports Analyst Intern
York University, Toronto
I query varsity football databases with SQL and Python and write the R code for 2 weekly coaching reports used in game preparation.
2026 to Present
Finance Executive
York University Data Science Club, Toronto
I reconcile purchases and reimbursements and prepare event budgets for a club of 120+ members. I report discrepancies to the Head of Finance.
May 2024 to Aug 2024
Financial Data Analyst Intern
Lekki Cooperative Multipurpose Society, Remote
I automated recurring Power BI reports on cryptocurrency rate movement, tracked with SQL. It saved about 40 hours a month and kept investors and senior leadership current.
Skills
Everything here is used in a project above, except the last box.
GenAI and agents
LangChain, LangGraph, RAG, prompt engineering, LLM evaluation, computer vision
ML and data
PyTorch, scikit-learn, PySpark, pandas, NumPy, feature engineering, cross validation
Cloud and tools
AWS, Docker, GitHub Actions, Git, PostgreSQL, dbt, DuckDB
Learning now
TensorFlow, Kubernetes, Kafka, AutoGen. Not in the projects yet.
Education and certificates
Expected 2028
York University
Bachelor's Degree, Data Science
Available for a 4 month work term from January 2027.
Foundations in Building Machine Learning Models IBM SkillsBuild
In progress
Machine Learning for Data Science Projects IBM SkillsBuild
In progress